Enterprise AI Training Data & Annotation
High-Quality AI Training Data & Precision Annotation
Humobot AI is a specialized data partner for machine learning enterprises advancing AI research and development. From bespoke data collection to pixel-accurate annotation and native transcription, we create high-precision training corpora for ASR, TTS, NLP, and computer vision—engineered to deliver the quality, scale, and accuracy your models demand.
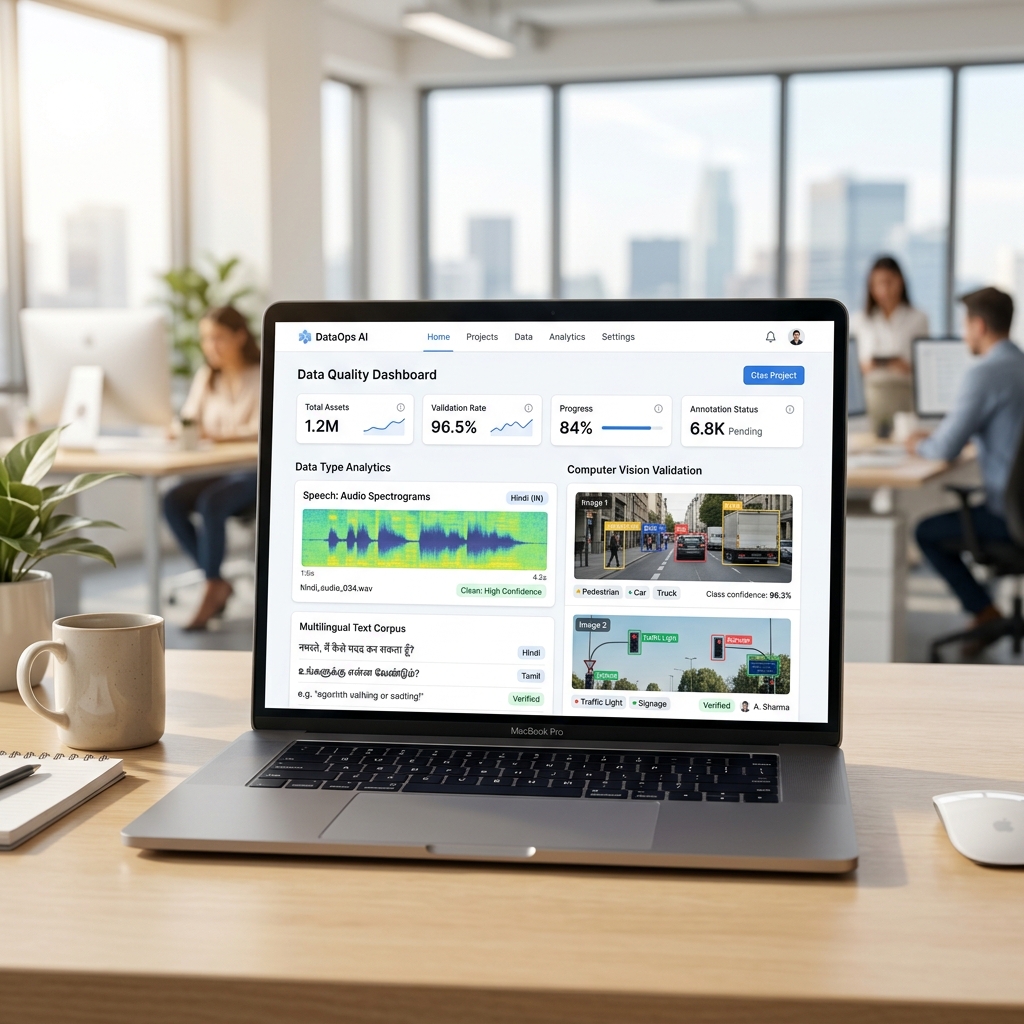
Applied Across High-Impact AI Application Domains
Enterprise Solutions
End-to-End AI Training Data Services
From bespoke data collection to pixel-accurate annotation and native transcription, we create high-precision training corpora for ASR, TTS, NLP, and computer vision—engineered to deliver the quality, scale, and accuracy your models demand.
Data Collection
Custom, scalable datasets tailored to your exact use case across voice, imagery, video, and text.
Data Annotation
Accurate labeling for text, image, audio, and video with human-in-the-loop quality control.
Speech & Audio Datasets
Real call center conversations and natural speaking patterns for ASR, TTS, and Voice Bots.
Transcription Services
High-precision audio-to-text across multiple languages, dialects, and noisy acoustic environments.
Translation & Localization
Native-level translations and cultural adaptation to help your conversational AI go global.
Ready-to-Use Datasets
Instant-access, pre-structured training datasets to accelerate your time-to-market.
Linguistic Diversification
20+ Indic Languages. Global Speech Corpora.
Train robust voice and language models with high-fidelity speech data. Access deep, diverse coverage across 20+ Indic languages, alongside extensive speech datasets spanning European, Southeast Asian, and Middle Eastern languages.
Why Humobot AI
Built for Scalable, Enterprise-Grade Model Development
We bridge the gap between ambitious AI research and real-world performance with human-verified data pipelines and experienced project leadership.
Human QA Precision
Multi-tiered human verification with rigorous validation on every single sample before dataset handoff.
Languages & Dialects
Deep, diverse coverage across 20+ Indic languages, alongside extensive speech datasets spanning European, Southeast Asian, and Middle Eastern languages.
Consented & NDA Protected
Strict participant consent protocols, fair compensation, and bilateral non-disclosure agreements for enterprise security.
Rapid Pilot Turnaround
Agile project management teams across India ready to fulfill custom pilot batches and scale to millions of annotations.
Enterprise Compliance & Data Governance Standards
Participant consent logs, NDA protection, and full adherence to international data privacy regulations.
Stop Collecting. Start Training.
Tell us your model's exact data needs across voice, text, imagery, or video. Our specialized teams collect, annotate, and deliver ML-ready datasets on schedule.
Fast turnaround • Custom data collection protocols • 20+ Indic & global languages supported